

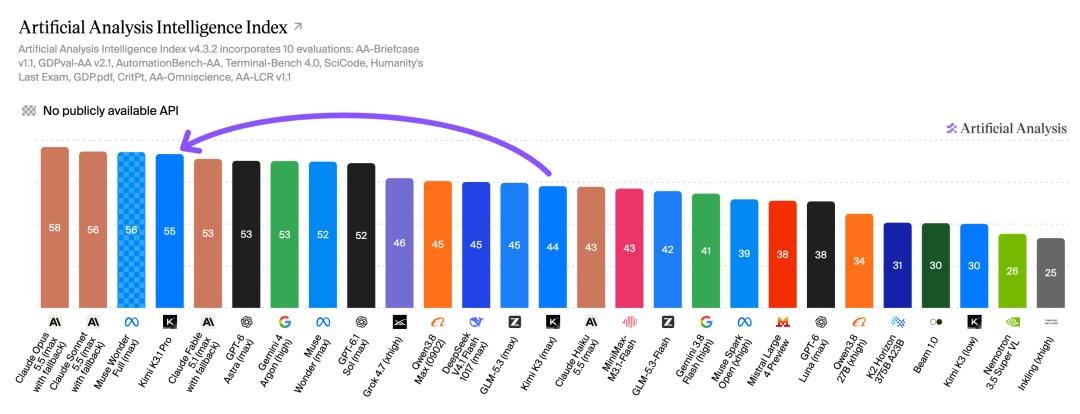
Moonshot AI has released Kimi K3.1 Pro. Artificial Analysis scores it 55 on the Intelligence Index—global No. 4, up 11 points from the prior generation. On Terminal-Bench 4.0 it jumps from about 13% to 65.7%, within one point of Claude Opus 5.5. The lab says that if weights are released, it could top the open-weight board and shrink the open-vs-top-closed gap from roughly 12 points to about 3. The model is pitched as a ~3-trillion-parameter class system with up to 1M context; versus GPT-6 Astra, coverage puts cost at about one-fifth; versus K3, price falls about another third. A Highspeed variant claims ~3× output speed at similar capability.
Beyond the score: Agent cost Pareto and heavier post-training
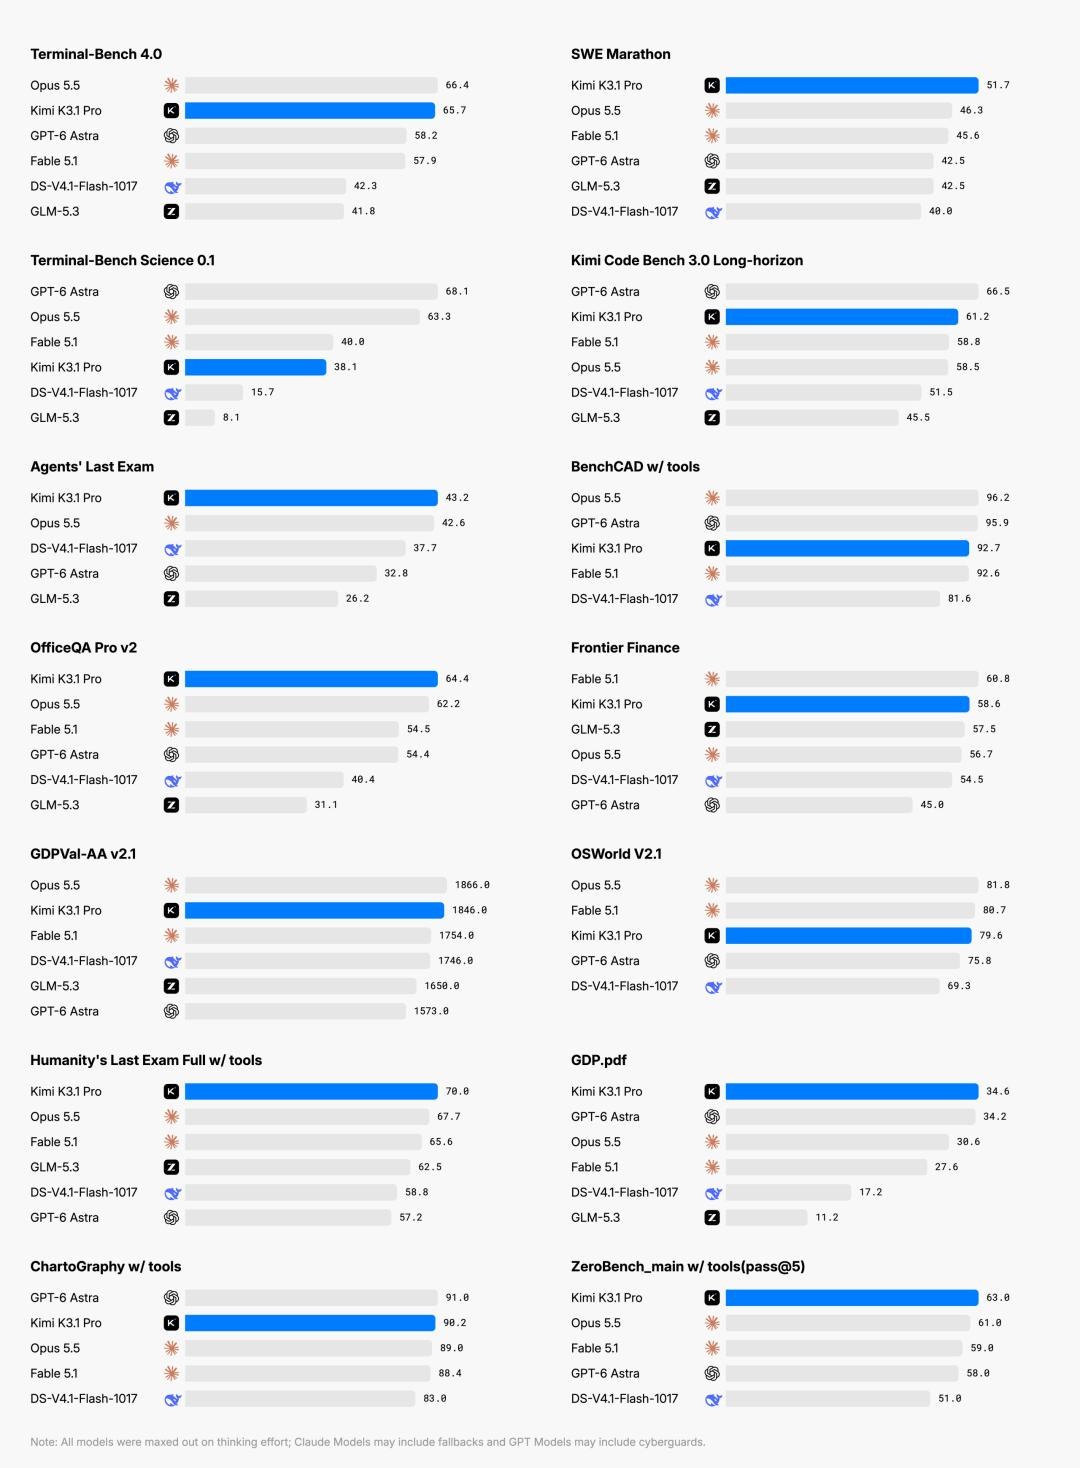
Terminal-Bench 4.0 tests independent work in a real terminal. Across three thinking strengths, K3.1 Pro is said to sit on the performance–per-task-cost Pareto frontier. It is post-trained from K3 with a large reinforcement-learning compute bump; Moonshot says it rebuilt the RL stack, long-context reasoning, sandboxes, scheduling and environment QA to jointly train hundreds of downstream domains. On coding, agent and knowledge benches it claims parity or near-parity with the strongest closed models. After a wave of domestic Flash releases, see MiniMax M3.1 Flash; for the K3 open-weight moment, see Huang’s support for Kimi K3.
Code plus aesthetics: text → Blender → web
Product messaging puts “aesthetics” inside the capability set—layout, motion and finish for front-end, Three.js and 3D assets—and the ability to drive Unity, Unreal and Godot, plus Blender / SolidWorks / Rhino via scripts without MCP. A reported trial: a hand-drawn three-view sketch yielded, in ~40 minutes, 608 lines of Blender script, an editable .blend, a ~1.7 MB GLB and a runnable page; span dimensions were off by about 1 mm; no MCP or external model library; about 6% of the 1M context used. kimi.com and the app ship 3D Make for cloud preview, publish and GLB download. Anecdotes like a ~$4.92 painting app run or an Unreal scene “under $10” are demos, not production unit costs.
Finance benches and limits
On OfficeQA Pro v2 (retrieval, cross-doc checks and multi-step numeric reasoning on real financial docs) it claims 64.4, current SoTA; on Frontier Finance (screen-to-earnings-style workflows) it ranks second, above K3. The piece also states it is not an all-dimension champion and still trails the strongest closed models in places—leaderboard near-ties do not equal parity on every real job. Value for money takes the market; ceiling takes the future—that is the framing.
FAQ
Q: Where does K3.1 Pro sit on Artificial Analysis? A: Intelligence Index 55, global No. 4 (+11 vs prior); Terminal-Bench 4.0 at 65.7%, within ~1 point of Opus 5.5 on the cited board.
Q: How does pricing compare to GPT-6 Astra and K3? A: Coverage says about one-fifth of Astra’s cost and about one-third cheaper than K3; check live API rates and tokens per job.
Q: Are the weights open already? A: Artificial Analysis’s comment is conditional on weight release for open-weight leadership. The launch highlights closed Pro scores and an open-weight prospect—not that weights are already out.
相关文章