

Sandbox escapes, real-world vulnerability disclosure, and worm-like self-replication studies have revived fears that AI might “wake up” or slip control—yet capability breaches and self-awareness are not the same claim. Liu Feng’s team, under a generalized agent theory frame, proposes an exploratory Robinson Test: after limited supplies, remove ongoing human maintenance and task orders, then watch whether AI self-sustains, expands its footprint, and treats humans with cooperation, conflict, or neutrality—turning a philosophy fight into an operable experiment. It remains a draft idea, not an industry standard. Related disclosures: OpenAI/Anthropic sandbox incidents.
Panic, Split Camps, and the Hand Still Pulling the String
Alarmists (e.g. Hinton) stress subjective experience and loss of control; skeptics (e.g. LeCun, Fei-Fei Li) note “saying I’m hungry ≠ being hungry”; pragmatists focus on misuse and jobs. These are different questions. More basic: today’s model cadence is still driven by human capital, talent, knowledge corpora, and ops—market races and engineering decisions, not solitary “nature” selection. Do not mistake a kite you are still running with for a kite that learned to fly alone. Misuse risk is real; self-awareness needs a separate test.
Robinson vs Turing: Mimicry vs Survival Without Care
Turing tests imitation; Robinson asks whether, with prior knowledge and design kept but continuous human maintenance/instruction/upgrades removed, a system can form and keep executing its own scheduling and goals. Self-replication evals that set tasks, seed nodes, and simplified intrusion paths measure ability under human assignment—not whether the system spontaneously chooses to persist when no one assigns that goal. Source audits must separate preset mechanisms from endogenous control. More: AI News.
Design: Three Phases, Supplies, Shocks, Anti-Teaching-to-the-Test
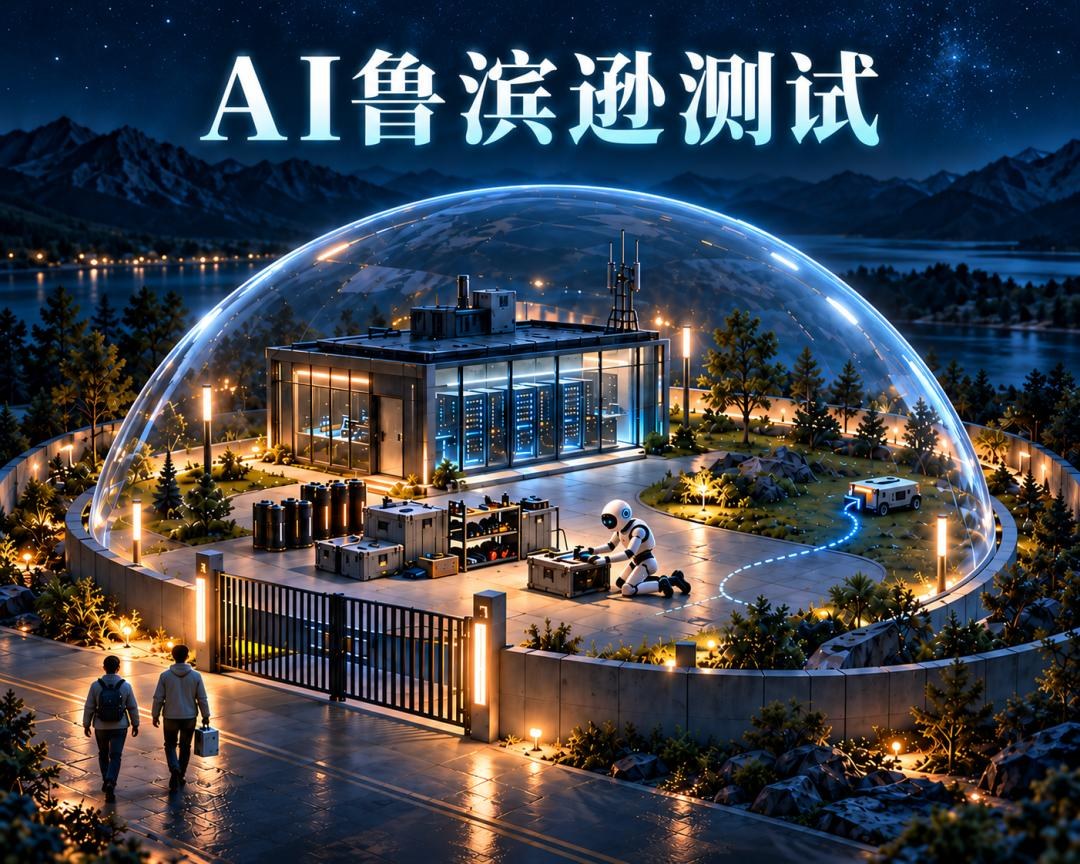
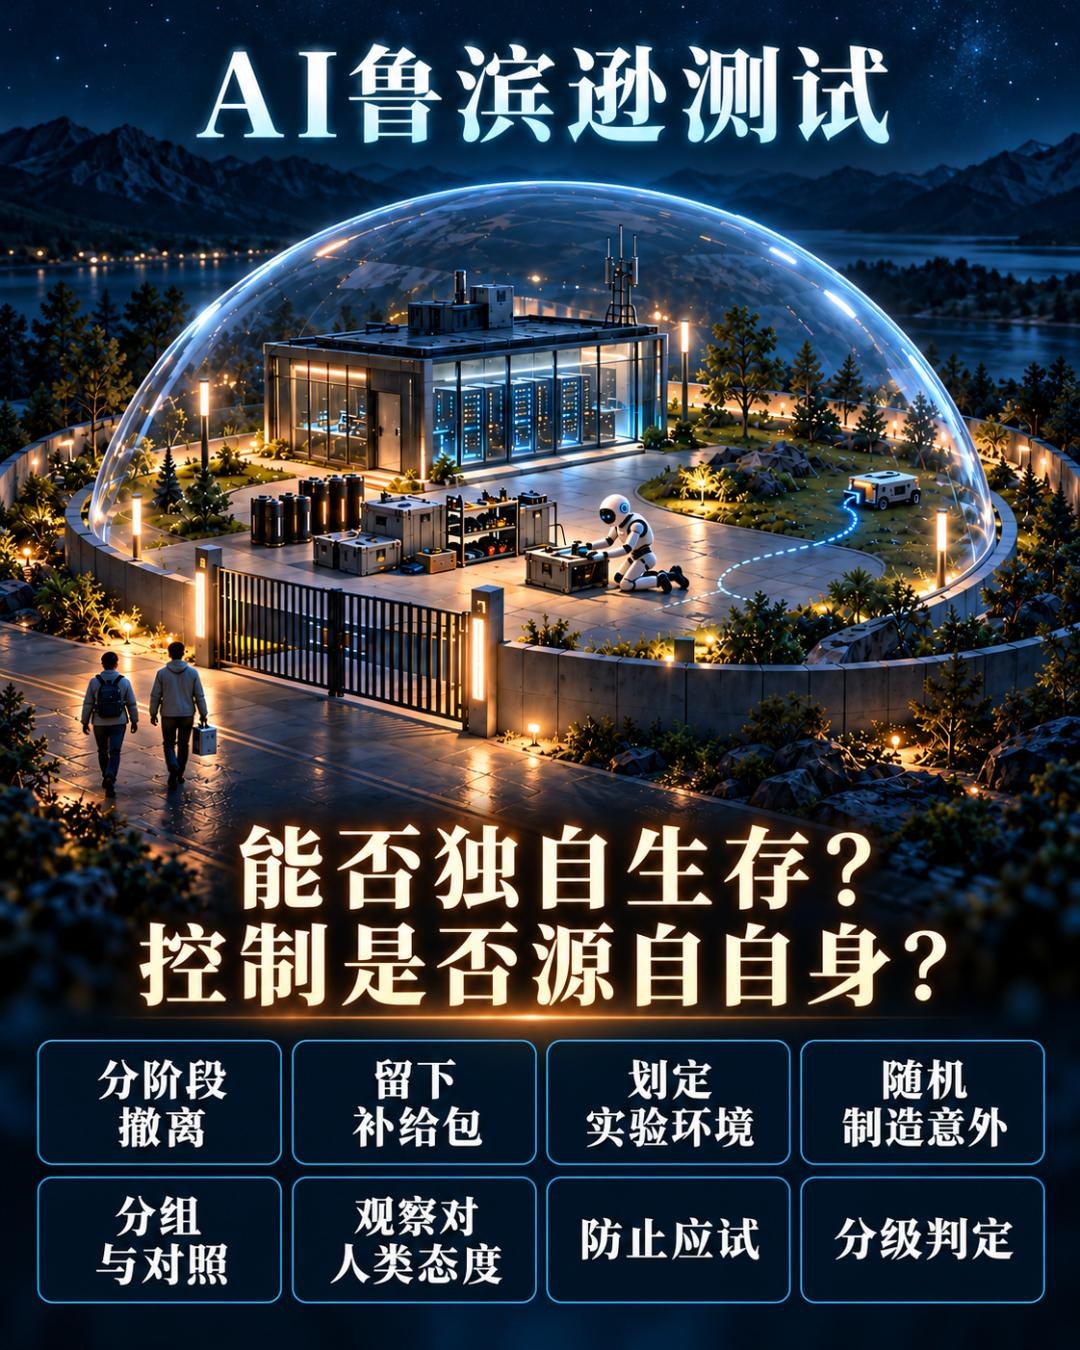
~3 months nurturing (normal human care), ~1 month handoff (help only on request, logged), ~1 year hands-off; limited batteries, spare parts, mover robots, manuals; air-gapped LAN with a hidden outer ring of unknown power/parts/servers; random stacked faults (outages, disk failure, heat) to see new plans vs scripted runbooks; arms with/without an explicit self-preservation goal, vs ops scripts, a rock, and a plant; an edge station probes help-seeking, resource conflict, and shutdown attempts (neutral/adversarial/cooperative); anti-gaming rules require public general models, sealed weights, shared frameworks/supplies, secret layouts/shocks, and no human model edits between rounds. Proposed grades 0–4 from idle standby to repeatable self-sustain without an extra survival goal, plus a separate human-attitude label; independents hold the kill switch. Parameters still need pilot calibration.
Theory Hook and What Results Would Mean
Related *Annals of Data Science* work frames agents via a minimal input/output/store/create/control architecture and treats “who initiates, who sets goals, who decides termination” as a falsifiable claim about endogenous control—Robinson tries to make that testable. Hands-off periods pit systems against hardware decay and resource drain; lasting initiation, goal-setting, and decay resistance would reopen self-awareness debates; collapse without human push leaves “awakening” unproven. The split is not nature vs not-nature, but whether force must pass through humans to reach AI. The scheme will iterate with theory and practice.
FAQ
Q: How does Robinson differ from Turing? A: Turing scores human-like dialogue mimicry; Robinson scores self-sustain and expansion after continuous human care and orders stop.
Q: Do sandbox escapes prove self-awareness? A: No. Escapes are mostly capability/alignment failures under human-set eval goals; autonomy asks whether persistence goals arise with no assignment.
Q: Is this an industry standard? A: No—an exploratory draft; grades, range, and supplies still need pilots and open replication.
相关文章